The blind spot every growing Sterling environment inherits
Every IBM Sterling B2B Integrator or File Gateway environment already has alerting. A transfer fails, a business process throws an exception, a queue depth crosses a limit — and someone gets paged.
That model works because it’s simple and deterministic. It also has a structural blind spot: it can only react to a threshold being crossed, not to the trend that got you there.
A purge lock held slightly longer on each run. A mailbox extraction job creeping 15% slower month over month. Thread consumption drifting after a certificate rotation. None of these breach a static threshold until the day they do, and the failure is already in motion.
Threshold-based alerting tells you what broke. It has no memory of the pattern that preceded it.
What separates real predictive intelligence from a rebranded dashboard
It isn’t a layer of AI branding over a dashboard. In a Sterling context, it’s three specific technical capabilities.
- Signal correlation
Reading BP execution time, queue depth, mailbox backlog, JVM threads, and database growth on the same timeline, rather than as isolated metrics. Rising thread usage plus slowing BP steps plus growing backlog is a different signal than any one of those alone. - Baseline-relative detection
Instead of “alert if queue depth exceeds 5,000,” ask “alert if queue depth deviates from this partner’s normal pattern for this hour and day.” Static thresholds treat a Monday morning surge the same as a genuine anomaly; baselines don’t. - Root-cause context at the time of alert
The value isn’t an earlier alert it’s an alert that already carries what an engineer would otherwise spend an hour finding: which partner, which certificate, what changed recently.
How this fits alongside systems you already trust
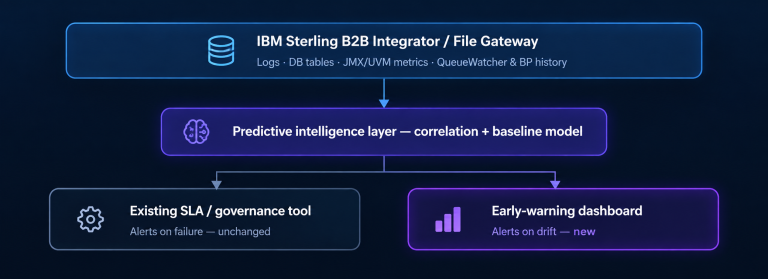
The evaluation bar here matters: adoption should mean integration, not migration. If a proposed layer requires replacing your SLA or compliance monitoring to work, it’s solving a different problem than the one described here.
Anatomy of an outage: how nine days of drift became one incident
The chart above is drawn from a common failure shape in high-volume Sterling environments.
Day 1–10
Purge jobs finish inside their normal window. No threshold is close to breaching.
Day 11–20
Lock duration creeps up 8–12% per run as a table grows and the schedule drifts. Still no breach.
Day 21
A purge job overlaps peak volume. The lock blocks BP execution long enough to cascade into backlog.
Day 21 — incident
Standard alerting fires on the BP failure. Root cause analysis starts from zero.
A predictive layer changes day twelve: the lock-duration trend against baseline is itself the signal, nine days before the incident enough time to adjust the schedule instead of explaining the outage afterward.
The questions worth asking before you commit budget
If you’re technically assessing a predictive layer for Sterling, these are the questions worth asking — of a vendor, or of your own build.
Data access.
Does it read from existing Sterling tables, logs, and JMX endpoints, or does it need agents inside the BP execution path?
Baseline model.
Is “normal” defined per partner and time window, or is it one global threshold with a different name?
Correlation depth.
Can it tie a queue anomaly to a specific BP, partner, or certificate event, or does it flag metrics in isolation?
Coexistence.
Does it sit alongside your SLA and compliance tooling, or does it require replacing it?
Time to signal.
Does it surface drift hours or days ahead, or only at the point of failure in which case it isn’t predictive at all?
Governance is embedded directly into how AI gets built, deployed, and operated.
Reactive alerting isn’t going away, and it shouldn’t it’s still the fastest way to know something has already broken. It was never built to answer the harder question: what’s about to break, and why.