Machine learning is becoming increasingly popular for tackling real-world challenges in practically every business domain. It aids in the solution of problems involving data that is frequently unstructured, loud, and large. Solving machine learning issues using standard techniques has become increasingly difficult as data quantities and sources have increased. Spark is a MapReduce-based distributed processing engine that solvesbig data and processingchallenges. Before getting into our topic, glance at this What is Apache Sparkthat will teach you how to construct Spark apps using Scala programming. You will learn the methods for boosting application performance, and Spark RDDs can be used to enable high-speed processing and aid with Customization provided by Spark using Scala.
Spark is abig data processingengine noted for being quick, simple to use, and general. Like Hadoop MapReduce, the distributed computing engine has processed and analyzed enormous amounts of data. When it comes to data handling from diverse platforms, it is far faster than other processing engines. Engines that can process activities like those listed above are in high demand. Today or tomorrow,
your organization or client will be expected to create sophisticated models that will allow you to identify a new opportunity or risk connected with it, and Pyspark can help you achieve just that. It is not difficult to learn SQL and Python, and it is simple to get started.
Pyspark is a Python and Sparkdata analysistool produced by the Apache Sparkcommunity. Python enables you to interact with DataFrames and Resilient Distributed Datasets (RDD). Pyspark includes various features that make it simple and an excellent machine learning framework in MLlib. Pyspark offers rapid and real-time processing, flexibility, in-memory calculation, and various additional advantages for dealing with large amounts of data. In simple terms, it’s a Python-based library that provides a channel for using Spark, combining Python’s simplicity with Spark’s efficiency.
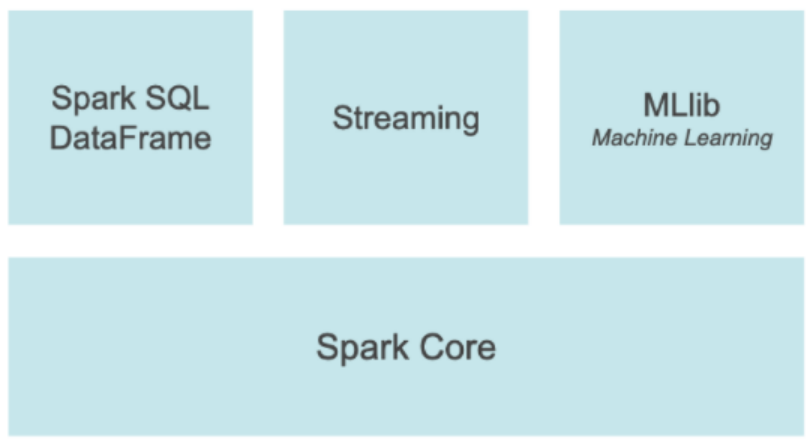
Let’s look at the PySpark architecture as described in the official documentation.
It offers a PySpark shell for interactively studying your data in a distributed environment and allowing you to create apps using Python APIs. Most Spark capabilities, such as Streaming, MLlib, Spark SQL, Data Frames for Spark core, and machine learning, are supported by PySpark.
Let us take a closer look at each one separately.
DataFrame and Spark SQL:
It’s a module that allows you to process structured data. It provides a DataFrame abstraction and also functions as a SQL query engine.
MLlib:
MLlib is a high-level machine learning toolkit with a collection of APIs to assist users in creating and tuning realistic machine learning models; It has almost all methods, such as collaborative filtering, regression, and classification, supported.
Streaming:
We can analyse real-time data from numerous sources using the streaming capability and then transfer the processed data into system files, databases, or even the live dashboard.
Spark Core:
Machine Learning Code Implementation Using Apache Spark
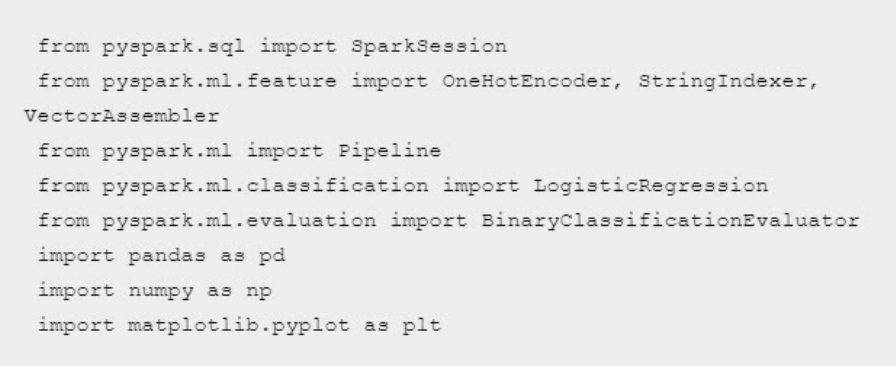
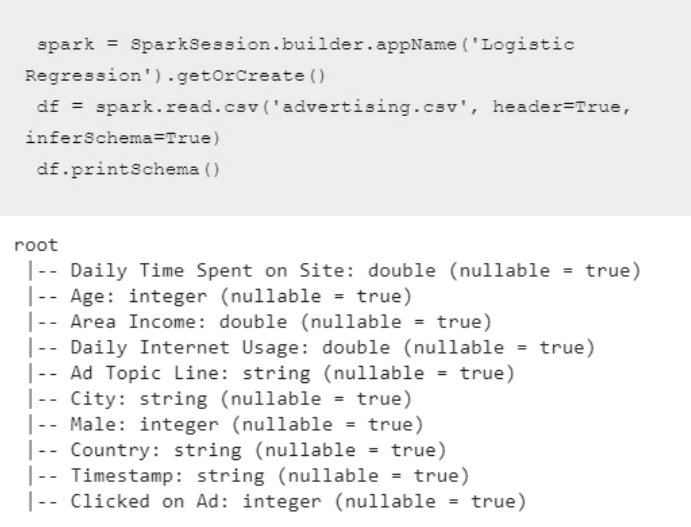
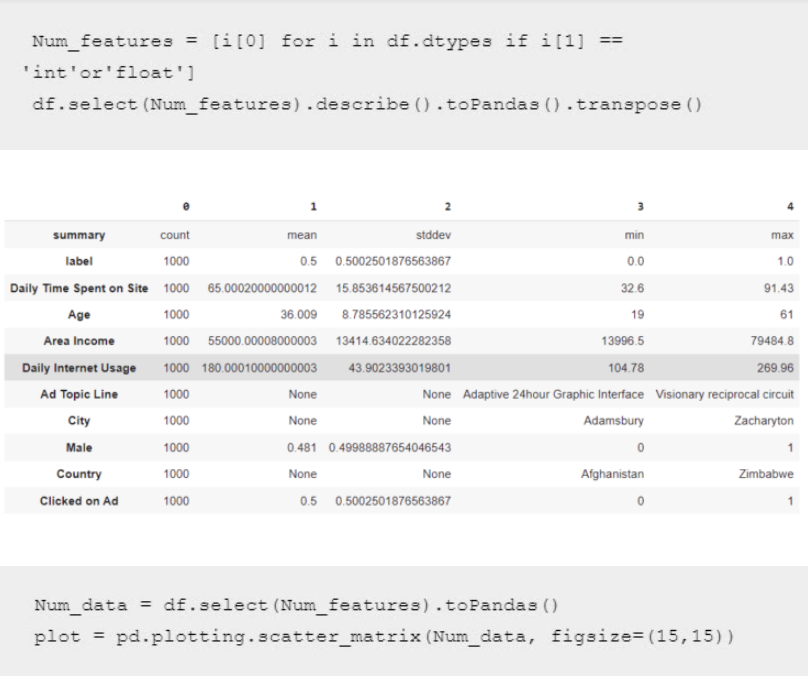
The dataset came from the Kaggle repository and has connected to Advertisement, which means we need to figure out which type of user is more likely to click on an ad.
ML data preparation:
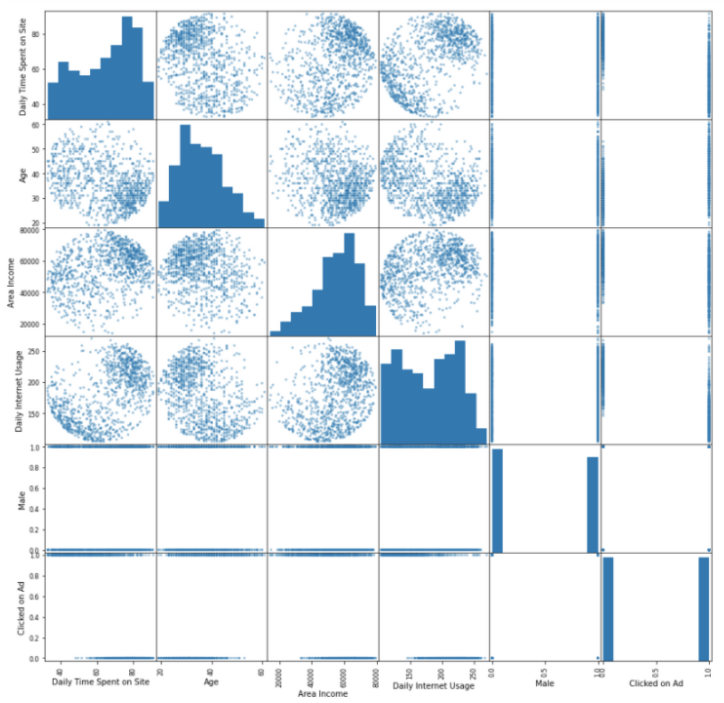
We can observe no multicollinearity connected with any of the features in the preceding correlation graph. Therefore we use all of them for further modelling. Categorical indexing, one-hot encoding for Categorical features, and Vector Assembler, which merges numerous columns into vector columns, are all part of the preparation.
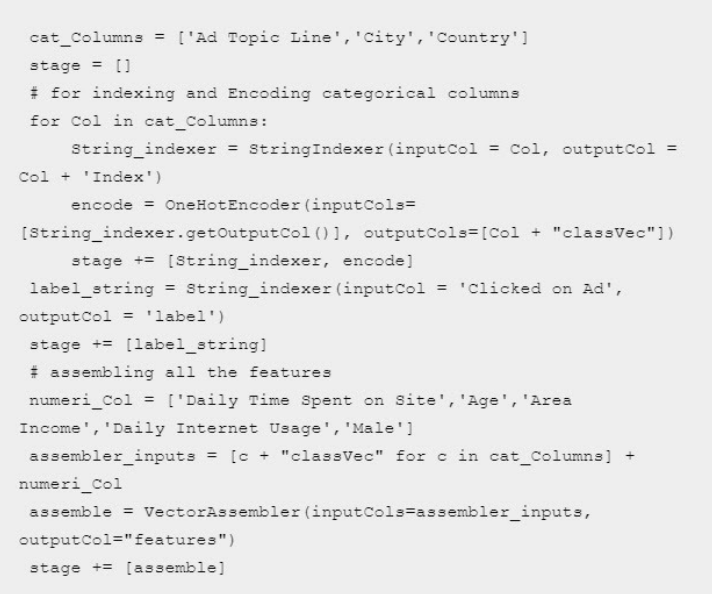
Pipeline:
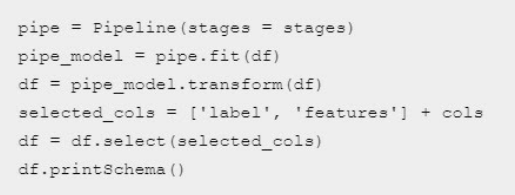
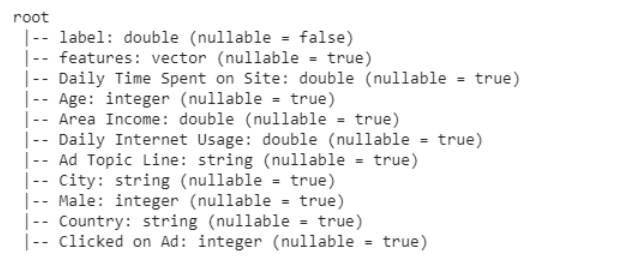
As mentioned earlier, the pipeline connects the various transformers and prevents data leakage.
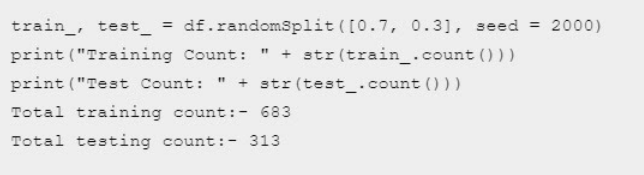
Splitting thetrain test:
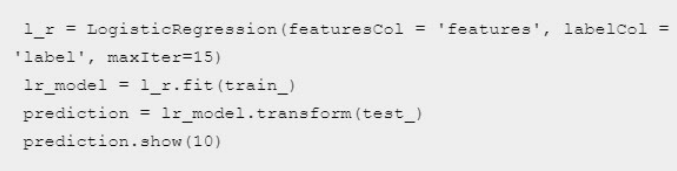
Loading & fitting the Logistic regression Model:
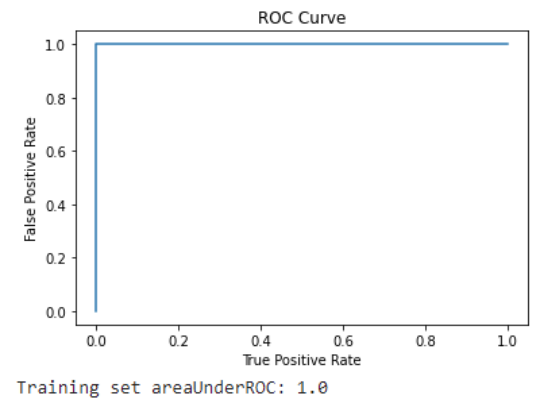
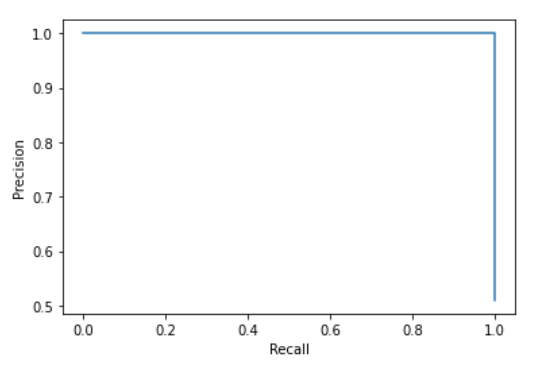
Let’s Plot some Evaluation metrics such as Recall Curve and ROC:
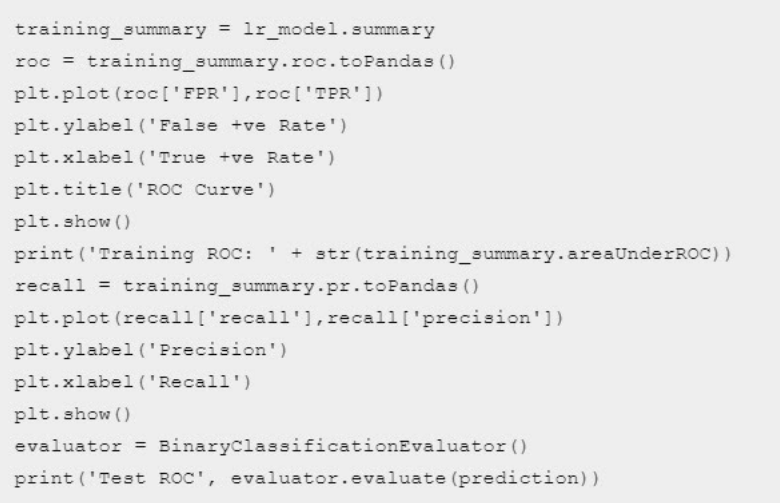
Outputs:
Test ROC: – 0.93
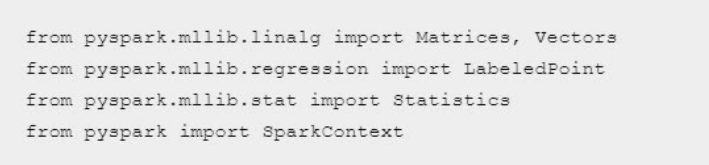
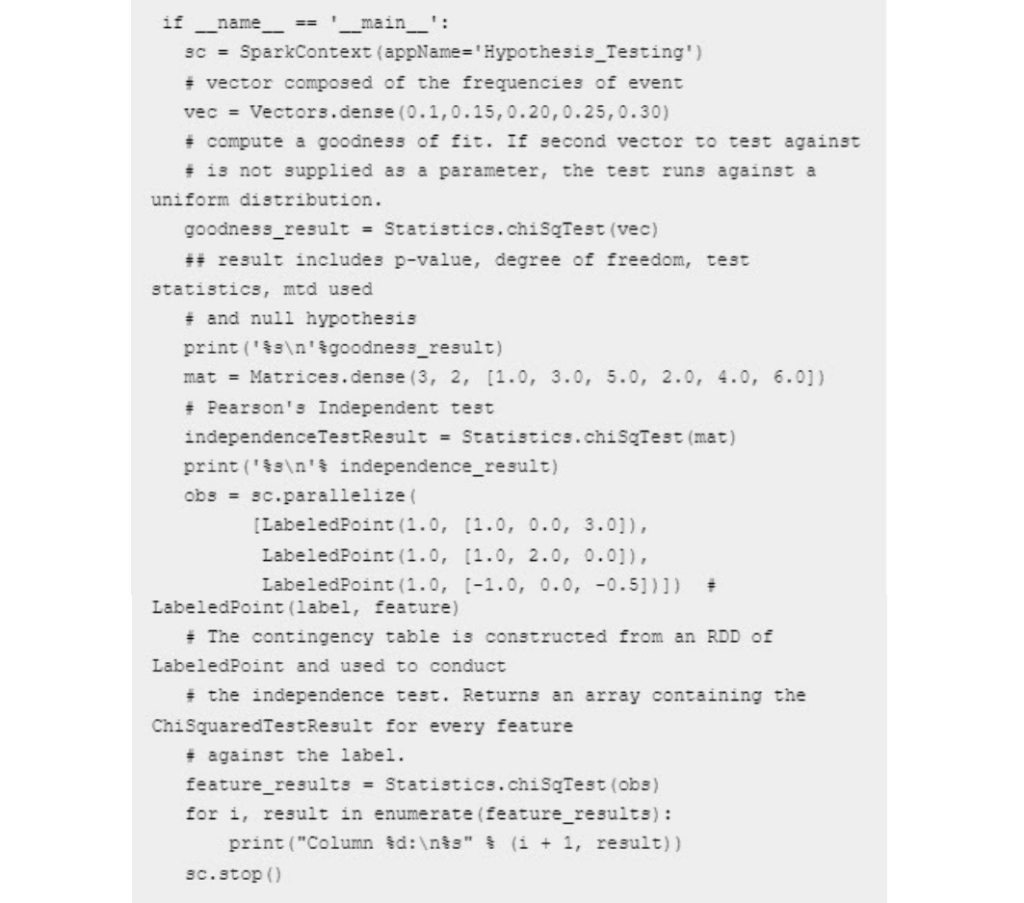
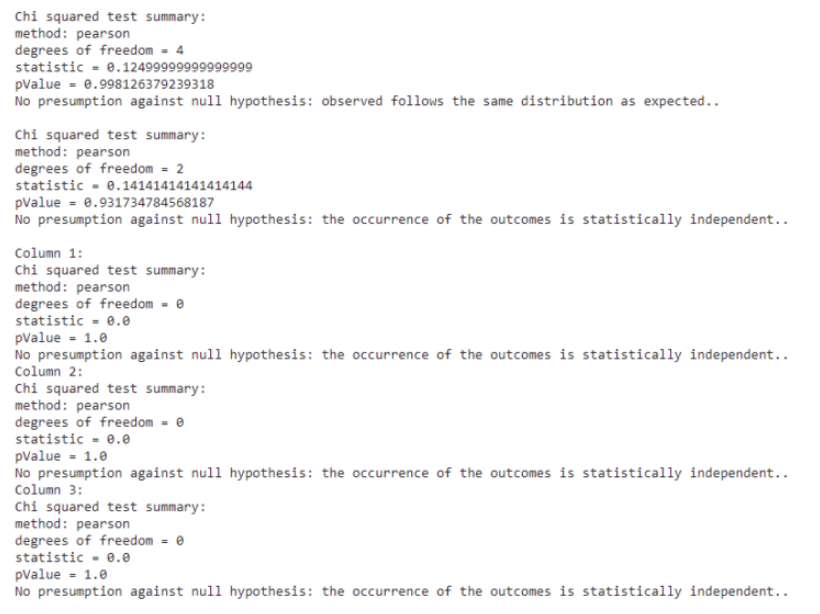
Hypothesis testing example:
Conclusion:
We’ve seen Spark’s overview and its features in this post. Then, in more depth, we learned how to use Pyspark API to manage CSV files, plot the correlation using the collected dataset, and prepare the dataset so that the algorithm can manage pipeline creation, model development, and model evaluation. Finally, we’ve seen how to use the ChiSquare Contingency test to conduct hypothesis testing. In the Notebook, there are many more examples of ML algorithms.